APIs can stop working in the middle of a checkout, and you won’t see it until a customer complains. That gap hurts revenue and trust. Below is a step‑by‑step guide that takes you from mapping your integrations to fine‑tuning alerts, so you catch problems before they bite.
Step 1: Map Your Critical API Integrations and Workflows
First, list every external and internal API your business depends on. Think of payment gateways, authentication services, inventory feeds, and any custom micro‑service calls. Write each endpoint, the request method (GET, POST, etc.), and the business action it enables, for example, "Stripe charge endpoint → order confirmation".
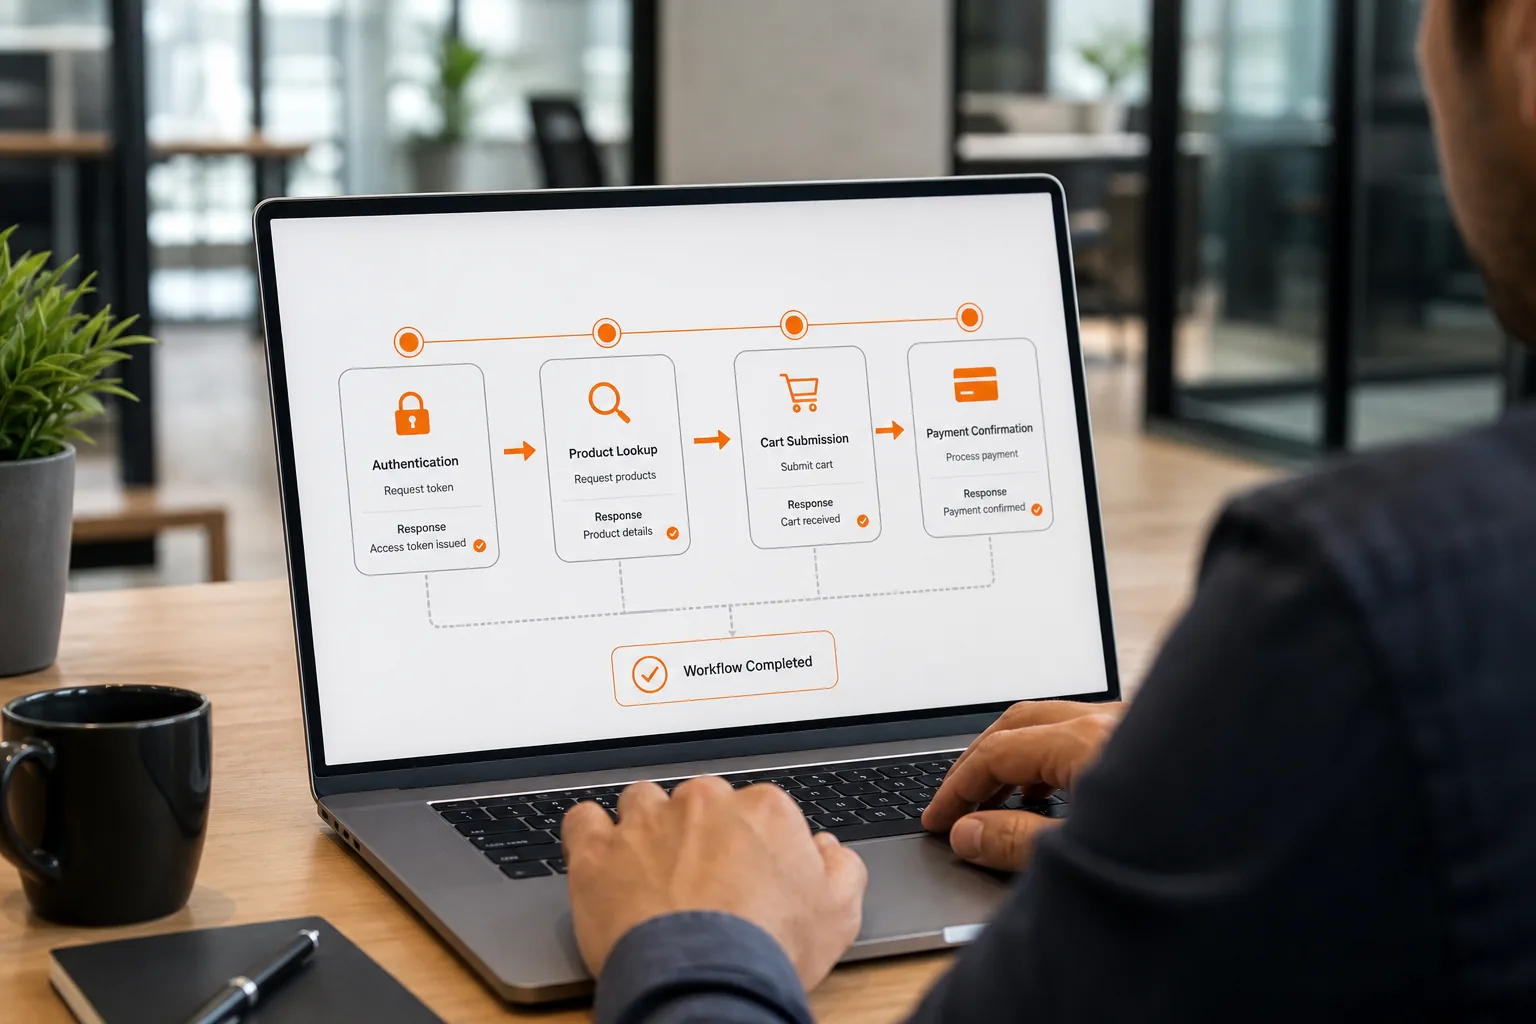
Next, draw the end‑to‑end flow. Use a simple diagram or a spreadsheet that shows the sequence: auth token → fetch product data → submit order → send confirmation email. This visual map lets you spot multi‑step transactions that need more than a simple uptime check.
When you know which calls are high‑value, you can prioritize monitoring resources. A checkout flow that moves $50 per order should sit at the top of the list, while a background analytics ping can wait for a later pass.
We often start with a quick audit of existing documentation. If you already have OpenAPI specs, import them into a spreadsheet, it saves time and guarantees you capture every path.
By the end of this step you have a master list of APIs, the order they run in, and a clear picture of which flows matter most to your bottom line.
Step 2: Choose the API Health Signals and Alert Thresholds to Track
Now pick the metrics that actually tell you whether an API is healthy. Availability (up/down) is the baseline, but you also need response time, error‑rate, and payload validation.
A 200 OK response alone isn’t enough; verify the data, latency, and the full transaction chain. For each endpoint, set a baseline for P95 response time and then alert when latency spikes to double that value. For error‑rate, a rule of thumb is to fire an alert if the rate exceeds 2 % of total calls over a five‑minute window.
Don’t forget content checks. Use JSONPath or XPath assertions to confirm that the response contains required fields, for example, the "status" field should be "success" after a payment request.
Define severity levels. A warning for a minor latency increase lets you investigate before things break, while a critical alert for a 500 error should page the on‑call engineer immediately.
Finally, tag each alert with the business impact, “checkout failure”, “inventory sync delay”, etc. That tag shows up in your incident board and helps the response team prioritize.
Step 3: Match API Monitoring Tools to Your Integration Needs
With signals in hand, compare tools against the checklist you just built and the capabilities in these API integration monitoring solutions. The table below lines up a handful of popular platforms, what they excel at, and the pricing model that matters for midsize teams.
| Tool | Best for | Private Monitoring | Free Trial / Plan | Starting Price |
|---|---|---|---|---|
| Datadog | Full‑stack observability with trace correlation | Yes | Free trial | $5 per 10,000 runs |
| Site24x7 | Global multi‑step API checks on a budget | Yes | Free plan | $9/month |
| Checkly | Monitoring‑as‑code for engineering teams | Private locations (paid) | Free Hobby tier | $24/month |
| Pingdom | Simple uptime alerts for non‑technical users | No | Free trial | See website |
For most US SMBs, the mix of Datadog, Site24x7, and Checkly gives you the core features you need without surprise fees.
When you compare a tool to your checklist, ask: does it let me run multi‑step scripts? Does it support private agents for internal services? Does the pricing model fit my expected run volume?
Once you pick a vendor, we can help you spin up a pilot environment and verify that the alerts fire as expected.
Step 4: Configure API Checks, Workflow Tests, and Actionable Alerts
Start by creating a simple health check for each endpoint: an HTTP GET that expects a 200 response and a JSON field called "status" with the value "ok". Most tools let you copy‑paste a cURL command or use a UI wizard.
Next, build a multi‑step transaction. For a checkout flow, the first step fetches an auth token, the second calls the product API, and the third posts the order. Chain the token from step 1 into step 2’s header, this mimics real user behavior and catches auth‑expiry bugs.
Set alert thresholds based on the numbers you recorded in Step 2. For example, if the P95 latency for the payment endpoint is 350 ms, configure a warning at 500 ms and a critical alert at 800 ms.
Make alerts actionable. Include the failing URL, the step that failed, and a snippet of the response payload. Route the notification to Slack, PagerDuty, or Teams so the right engineer sees it instantly.
Finally, enable escalation. If the first on‑call doesn’t acknowledge within five minutes, bump the alert to the secondary engineer and, if needed, send an SMS. This keeps incidents from sitting idle.
Step 5: Validate Monitoring, Triage Incidents, and Refine the Setup
Run your new monitors for at least a full business day. Watch the dashboards for false positives, an alert that fires on a harmless 404 from a deprecated endpoint is noise you want to silence.
When a real failure occurs, follow the alert to the linked trace or log and use a step-by-step API integration error troubleshooting workflow to trace the issue. If the tool offers integrated APM (like Datadog), you’ll see the exact database query that slowed the response. Use that insight to fix the root cause, not just the symptom.
After each incident, update your thresholds. If a latency spike turned out to be a harmless load‑test, raise the warning level to avoid future fatigue. Conversely, if a minor error caused a revenue drop, tighten the alert.
Iterate weekly for the first month. Each cycle should reduce alert noise and improve mean‑time‑to‑detect (MTTD). When you’re comfortable, hand the monitoring playbook over to the on‑call rotation.
Our team at Lakeway Web Development can audit your alert rules and suggest refinements, ensuring you get the right signal without the chatter.
Frequently Asked Questions
What is the difference between synthetic and real‑user API monitoring?
Synthetic monitoring runs scripted requests from fixed locations on a schedule, letting you catch failures before any real user is affected. Real‑user monitoring tracks live traffic, showing you how actual users experience the API. Synthetic checks are great for SLA verification; real‑user data adds context for performance tuning.
Do I need a separate tool for internal APIs?
Yes, internal services often sit behind firewalls, so you need a tool that supports private agents or on‑premise probes. Without that, you only see external failures and miss internal bottlenecks.
How often should I run multi‑step checks?
For critical checkout flows, a five‑minute interval balances speed and cost. Less‑critical sync jobs can run every 15 minutes or hourly. Adjust the cadence based on the business impact of each transaction.
Can I reuse my existing Postman collections for monitoring?
Absolutely. Many platforms (Postman Monitors, Checkly, and Datadog) let you import collections, turning your development tests into production‑level checks without rewriting scripts.
What’s a good alert‑noise ratio?
Aim for fewer than one false positive per week per engineer. If alerts feel noisy, raise thresholds, add more precise payload assertions, or filter out non‑critical status codes.
Conclusion
If you want reliable API health without endless manual checks, start with the five‑step workflow above and let Lakeway Web Development fine‑tune the final alert rules. Reach out to talk through your monitoring setup.